
SpeechmaticsEditorial team
Accuracy has been one of the main speech recognition challenges for many years – and a barrier to entry for many businesses. Historically, the technology hasn’t been considered good enough to adopt as an integral part of a workflow and technology stack. But that is simply not true anymore. Voice technology has now improved to a point at which the output for the most spoken languages in the world – such as English, French, Spanish and German – is highly accurate in terms of word error rate (WER). So, what other challenges are affecting the future of speech recognition? And why is accuracy still a problem? These are the barriers highlighted by respondents to a survey as part of the Speechmatics report on Trends and Predictions for Voice Technology in 2021: 1. Accuracy
These days, accuracy refers to more than just the accuracy of the word output – the WER. Many other factors affect the level of accuracy on a case-by-case basis. These factors are often unique to a use case or a particular business need and include:
Background noise
Punctuation placement
Capitalization
Correct formatting
Timing of words
Domain-specific terminology
Speaker identification
The past year has seen a huge increase in concerns about data security and privacy – from 5% to 42% in the Speechmatics survey. This could be due to mistrust following media portrayal of ‘data-hungry’ tech giants. It could also be a result of more day-to-day conversations happening online when the coronavirus pandemic led to an explosion in remote working.
Deploying and integrating voice technology – or any software, for that matter – needs to be simple. Whether a business requires deployment on-premises, in the cloud, or embedded, integration needs to be easy to do and secure. Without the appropriate support or documentation, integrating software can be time-consuming and expensive. It is, therefore, important for technology providers to make their deployments and integrations as frictionless as possible to avoid this barrier to adoption.
Many of the leading voice technology providers have a gap when it comes to language coverage. Most providers cover English but, when global businesses want to use voice technology, the lack of language coverage provides a barrier to adoption. When providers do offer more languages, accuracy is often still an issue when it comes to accent or dialect recognition. What happens when an American is speaking with a British person, for example? Which accent variation is used? Global language packs, encompassing a variety of accents, solve the problem.
Risks for speech recognition technology in the next 10 years.
Data privacy will continue to be a concern in the future of speech recognition, according to 95% or survey respondents. But there will be ways to overcome data security issues: Overcoming speech recognition challenges of data security 1. On-premises deployment
On-premises deployment of voice technology enables users to keep their data secure within their own environments – with no need for data to go into the cloud. It is often done using virtual appliances or containers so they can be deployed effortlessly into existing technology stacks. This is particularly important for industries such as banking, financial services and insurance where compliance and regulatory issues mean customer data and voice data cannot leave their premises. 2. Dark site environments
Typically, when deploying an on-premises solution for voice technology, businesses are required to connect to the public internet for licensing. Offline licensing is supported in dark site deployments – meaning all work is completed within an organization’s private environment. This delivers a more robust solution for compliance and data privacy needs. 3. Cloud deployment
Private cloud deployments are secure enough to keep data safe for lots of applications. If cloud deployment security is good enough for the business and use case needs, cloud deployment is often the preferred option due to low operational cost and less complexity. Want to know more about how to overcome speech recognition challenges? For more information – and the full survey results – download Trends and Predictions for Voice Technology in 2021.
The return of on-premise: Why enterprise AI's head is no longer in the cloud
Speech recognition software: Why Speechmatics is the most compelling choice
Your essential 2026 guide to voice ai compliance in today's digital landscape
AI personal assistant guide: How voice is powering enterprise success beyond
Kao Data to Host Speechmatics’ HPC and AI Supercomputer, Expanding Deep
Ten questions to Stuart Wood, Director of Product, on the economics of speech at scale, how close local accuracy now gets to cloud, and who could benefit from Speechmatics On-Device.

New ways to pay from October 1

End customers will only ever see their own provider's brand, which means the layer underneath has to be good enough to go unnoticed.
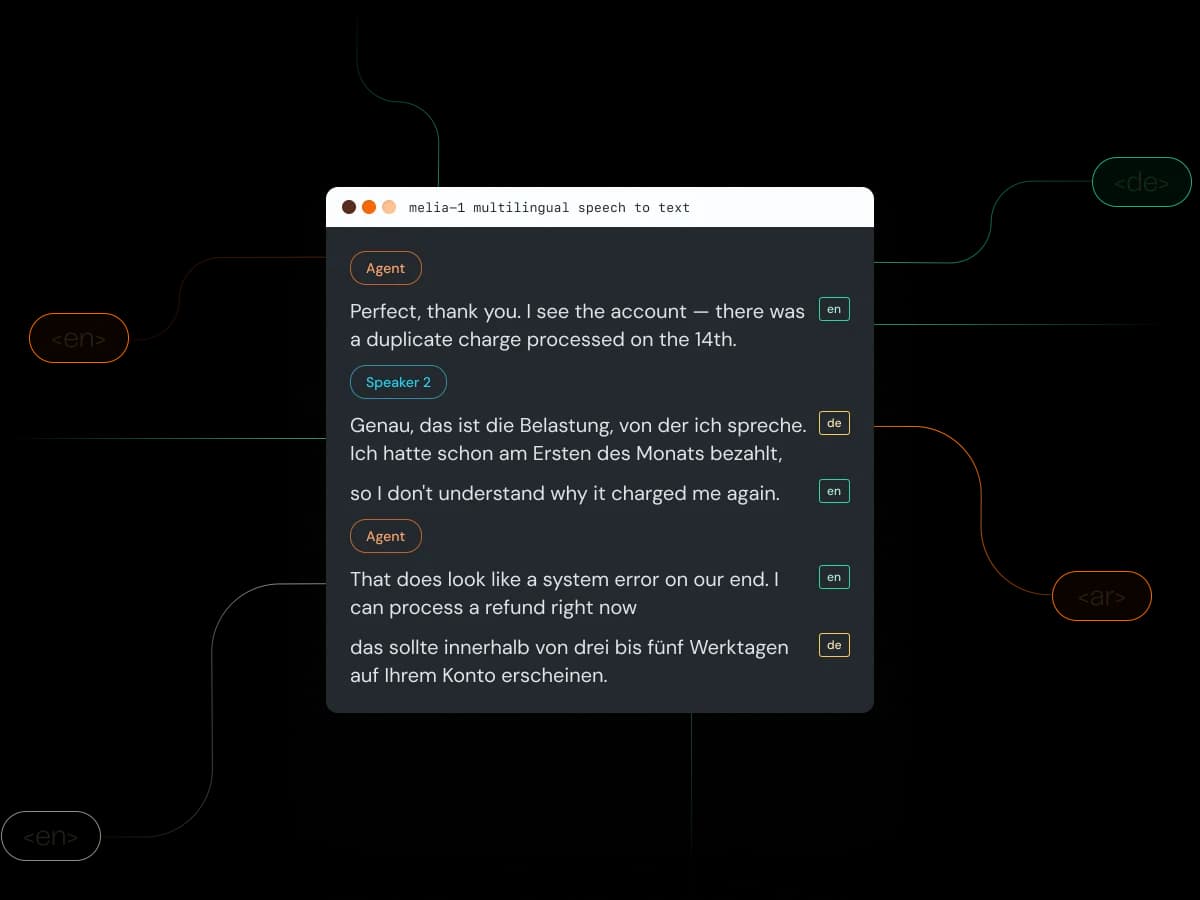
On Arabic and English, Melia 1 runs at less than half the mixed error rate of the next best model. On Mandarin and Tamil it switches more accurately than anything else we tested.

Linden, Speechmatics' new speech-to-text model built for voice agents, is now available through LiveKit Inference, no separate API key, account, or invoice required. Try it out now, click the circle to the bottom right of your screen.

An hour of audio in, a transcript back in under 20 seconds. 30 minutes in under 10 seconds. 10 minutes in under 5 seconds.