- Speech To Text
- On Device
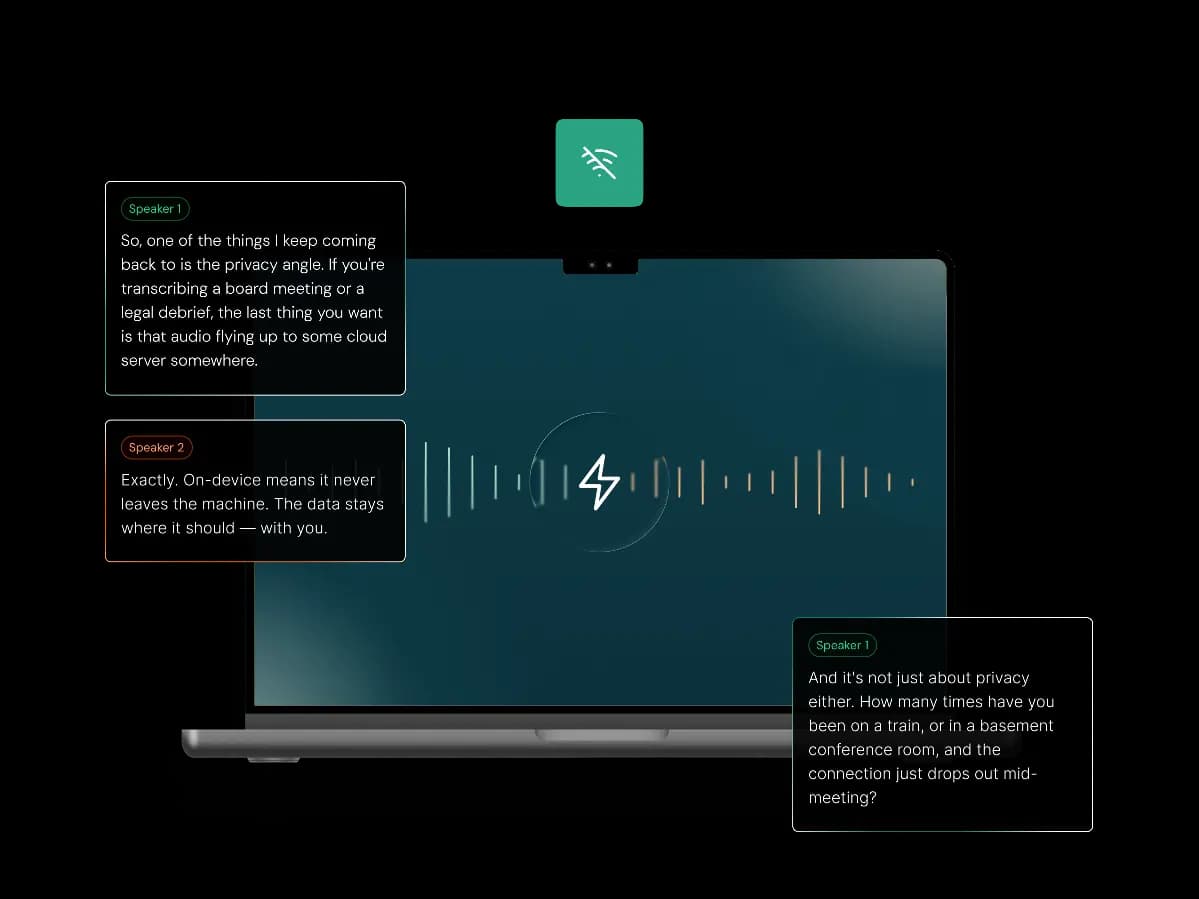
On-device speech-to-text for laptops.
Enterprise-grade Speech-to-Text running locally on Mac, Windows and other devices. Sub-second latency, no infrastructure costs and audio that never leaves the machine. Full speaker diarization and identification included.
✅ Runs on laptop hardware
✅ 55+ languages
✅ CoreML & DirectML optimized
Trusted by millions of users globally
Driving better conversations at scale
Leveraging speech recognition to track customer interactions, highlight key insights, and raise contact center performanceRedefining real-time captioning
Precise, low-latency transcription and translation, all delivered before your media even ends.Delivering 120X more with voice AI
Powering live content through AI-powered transcription, built on industry-leading voice AICloud-grade speech recognition on-device for Adobe Premiere
Run the most accurate on-device transcription locally; efficient enough for a laptop, powerful enough for professional work.Driving better conversations at scale
Leveraging speech recognition to track customer interactions, highlight key insights, and raise contact center performanceRedefining real-time captioning
Precise, low-latency transcription and translation, all delivered before your media even ends.Delivering 120X more with voice AI
Powering live content through AI-powered transcription, built on industry-leading voice AICloud-grade speech recognition on-device for Adobe Premiere
Run the most accurate on-device transcription locally; efficient enough for a laptop, powerful enough for professional work.Deploy enterprise STT on every laptop
Adobe and other ISVs build privacy-first, laptop-native applications with Speechmatics On-Device.
Tell us about your deployment and we'll follow up directly.
Why run offline STT on the laptop?
Reliable transcription regardless of network conditions, with data that stays private and features that match the cloud.
Offload transcription from cloud to the device
Predictable licensing model
Scale without scaling your server fleet
Works when Wi-Fi drops
Critical for clinical and legal environments
Sub-second latency, no network dependency
GDPR, HIPAA, and air-gapped ready
Compliance by architecture
Sell into regulated & government accounts
12-16% fewer errors than Whisper-based alternatives
Full speaker diarization and ID
55+ languages, real-time and batch
See it in action
Adobe has partnered with Speechmatics since 2021 for speech-to-text in Premiere.
The new on-device model delivers within 5% of cloud accuracy, processed locally and never leaving the device.
12-16% fewer errors than Whisper-powered alternatives.
Engineered for laptop silicon
Built for the Mac and Windows hardware your users already have.
Runs on Mac
Optimized for CoreMLRuns on Windows
DirectML optimized · GPU computeVideo editing & captioning
Local video editing tools with real-time transcription baked in. No uploads, no waiting, no cloud dependency.
Healthcare & legal scribes
Ambient scribe and dictation tools that keep working when hospital Wi-Fi drops. Patient and client data never leaves the device.
Regulated industries
Financial services, insurance, and legal. Sectors where compliance by architecture beats compliance by policy.
Government & law enforcement
Transcription where on-device processing simplifies security clearance and removes cross-border data transfer concerns.
Edge AI assistants
Deploy to devices, assistants, and enterprise systems without server costs or bottlenecks. Real-time, always available.
Note-taking & meetings
Meeting transcription that works in air-gapped environments, on flights, and in sensitive boardrooms.
Not all on-device STT is created equal
Speechmatics' on-device model matches its cloud model. Open-source alternatives ship stripped-down server models instead.
![[alt:A stylized horizontal bar graph comparing multiple values, with one central bar highlighted in a darker color to indicate a specific benchmark or result.]](/_next/image?url=https%3A%2F%2Fimages.ctfassets.net%2Fyze1aysi0225%2F4igMahU0DySDJ14ZJNarag%2F7f56cc660eb4b5a7698f3ca28b3672ff%2Fnear_cloud_accuracy_2x.webp&w=3840&q=75)
Cloud-parity accuracy
Our 2026 on-device model delivers the same accuracy as our cloud STT. Same architecture, distilled and quantized for laptop silicon with hardware-native acceleration.
![[alt:A digital transcript interface showing a dialogue between three speakers discussing a weather forecast, with text bubbles clearly separated by speaker labels.]](/_next/image?url=https%3A%2F%2Fimages.ctfassets.net%2Fyze1aysi0225%2FSbaj9GU7ropHDevlOG9Ns%2Ffc5756b1f3f12f10d03f53d9a0508a71%2Ffull_speaker_diarization_2x.webp&w=3840&q=75)
Full speaker diarization & identification
Includes our speaker diarization and speaker identification, with 12-16% fewer errors than Whisper-based alternatives.
![[alt:A realistic globe centered on the continents of Africa and Europe, floating against a green background with abstract curved lines.]](/_next/image?url=https%3A%2F%2Fimages.ctfassets.net%2Fyze1aysi0225%2F1LL0Tdp9fPAi7V1nw9d9zN%2F9d10876b7c29997830bc0114becf1c10%2Fenterprise_proven_2x.webp&w=3840&q=75)
Adobe runs it in production
Adobe Premiere has run Speechmatics on-device since 2021, alongside ISVs in legal, healthcare, and media production.
![[alt:A laptop device displaying an audio waveform visualization on its screen, with a location pin icon floating above to symbolize local processing or location services.]](/_next/image?url=https%3A%2F%2Fimages.ctfassets.net%2Fyze1aysi0225%2F5dWMUZSfzbO7g3FIPNnNZE%2F63b3d2a5c22635693055b8e1c12532a5%2Flocal_ai_shift_2x.webp&w=3840&q=75)
Built for on-device deployment
Speechmatics On-Device is a first-class deployment target, built for laptops from the ground up, not a stopgap until connectivity returns.
Offline speech-to-text FAQs
Pricing is based on your deployment volume and use case. Speak to our sales team for a tailored quote and volume-based discounts.
Operating System | Hardware requirements |
|---|---|
macOS v14 Sonoma or later, Tahoe v26 recommended | M1 or newer |
Windows 11 | Intel/AMD/ARM (with GPU 2GB) |
Other Hardware | Get in touch if you have different requirements |
Our 2026 on-device model has parity with the Speechmatics Standard cloud model. Same underlying architecture, distilled and quantized for local hardware. Includes full speaker diarization and speaker identification, with 12-16% fewer errors than Whisper-based alternatives.
The on-device model is compiled with hardware-native acceleration paths. On Mac, it leverages CoreML to run on the Neural Engine and GPU. On Windows, it uses DirectML for GPU compute. This means maximum throughput within a minimal resource envelope. No platform-specific code from your side.
Requires approximately 1 CPU core, an AI accelerator (Neural Engine on Mac, GPU on Windows), and ~800MB of system memory. No external GPU or dedicated inference hardware needed. Standard business and consumer laptops handle it comfortably. Contact us to learn more about specific deployment configurations.
![[alt: Laptop with speech-to-text feature showing speaker labels and audio waveforms on a dark screen with green accents.]](/_next/image?url=https%3A%2F%2Fimages.ctfassets.net%2Fyze1aysi0225%2F11lBXtT711R6DhmhAIp2eq%2Fab5ad419dfddcdbf447945541c00c8ef%2FOn-device-header-v2.webp&w=3840&q=75)