Stuart WoodDirector, Product
On-device speech-to-text runs entirely on the end user's machine, so cost stops scaling with usage once the engine is licensed.
Speechmatics On-Device gets within 5% of cloud accuracy, and beat comparable Whisper checkpoints by 12 to 16% in Adobe's 10-million-word evaluation.
Real-time streaming runs under 200ms on supported hardware, with the network round-trip removed entirely.
Cloud is still the right call when you need maximum accuracy, fast integration, or consistent performance regardless of end-user hardware.
The early-access waitlist is aimed at enterprise ISVs and OEMs shipping desktop apps for macOS or Windows with engineering resource to integrate a native C/C++ library.
After the response to our work with Adobe and Stenograph, we are opening up early access to try Speechmatics On-Device.
On-device speech-to-text runs on the end user's own device, with no audio sent to the internet or another server. Demand has been building along a few consistent lines: privacy and data sovereignty, transcription that keeps working with no network, predictable cost at scale and low latency by removing the network round-trip.
The pull is currently strongest in areas such as legal, media, healthcare, public sector, field work and high-volume note-taking.
We put ten questions to Stuart Wood, Director of Product, about what changed, where local transcription earns its place and where it does not.
Three things arrived at roughly the same time: quantization and optimizations improved to where a small model carries most of the quality of a large one, AI accelerators became standard across laptops and edge hardware to provide enough client compute, and customer demand shifted as local models resolved previously intractable cost, security, and compliance questions.
The shift in demand is often underestimated. As local summarization and on-device agents become viable on the same machine, keeping audio on the device moves from an awkward exception to a coherent architecture with speech input and intelligence running locally. Indeed, keeping the audio transcription local loses value if the transcript is immediately uploaded to a cloud server to use a remote LLM.
Having worked with Adobe on speech-to-text in Premiere, this is a proven foundation for us rather than a new bet. What is changing now is that we are releasing our technology as a general product across wider real-time and batch use cases.
They put the work in different places, and that changes what you have to build. On-device means a native library embedded inside your application, running on the end user's machine. Audio goes from the microphone or a file into that library and the transcript comes back. Nothing needs to leave the device, no audio or transcript touches a Speechmatics server, or yours either. On-device requires integration work and support running on end-user hardware. On-device means consideration of different operating systems (macOS, Windows, Linux, iOS, Android etc) and hardware differences (is only a CPU available? Does the device have an AI accelerator? How powerful is the hardware?).
On-prem means Speechmatics running in containers on your own infrastructure. Your data centre, private cloud or a local machine with Docker. The audio still usually leaves the end user's machine, it just travels to your server, not our SaaS. That distinction matters if your constraint is data residency (for example you need to keep audio in a certain company or country). It is no help at all if your constraint is that the device lacks a network connection or it's too poor to support real-time audio streaming. It has different considerations to on-device, the server hardware is under your control, you can serve requests at scale and expose our API for the end clients to use (it's the same API as in our SaaS). It also needs you to build and maintain the orchestration (we provide helm charts that help replicate our SaaS), and manage the infrastructure.
In practice the trade-off is about who carries which work. On-device removes the fleet of servers you would otherwise size for peak load, and replaces it with embedding a C/C++ library, managing its lifecycle, and shipping model updates through your own releases.
Teams that already build native desktop software can find it easier to embed into the application. For teams that do not, it is considerably harder. Also worth considering is whether the rest of your application logic requires network connectivity - in this case running speech-to-text on device may be less valuable for privacy.
It decouples product usage from cost. Cloud APIs offer a fast start, but every second processed is a second billed. Across a varied user base, transcription volume can fluctuate wildly from light usage to hundreds of hours per month per user.
With on-device, the marginal cost of additional audio drops to the hardware and energy consumption of the local machine. Operating expenses stop scaling with usage. For applications with a substantial install base, this transforms hosted API costs into a sustainable business model decision.
Another benefit is avoiding dedicated cloud infrastructure. You avoid running inference GPU servers, planning capacity for peak traffic, or scaling infrastructure during enterprise rollouts. Consider an all-hands meeting where a hundred attendees run local AI assistants: with cloud processing, hosting costs spike; on-device, your infrastructure load remains unchanged.
This transition requires initial engineering investment in exchange for long-term operational savings. For lower transcription volumes, cloud APIs remain highly cost-effective and straightforward. On-device deployment delivers the strongest return for organizations managing expanding transcription expenditure.
It simplifies data governance and compliance. Enterprise deployments often involve security reviews addressing audio processing locations, regulatory jurisdictions, data retention, and access controls.
When processing occurs entirely on the local machine, remote compliance risks are minimized by design. Local execution aligns with GDPR, HIPAA, strict data sovereignty frameworks, and air-gapped security environments.
Organizations and end users increasingly require clarity regarding data usage and model training. Processing audio locally provides structural assurance that raw audio data never leaves the device.
Beyond regulatory compliance, offline environments such as courtrooms, clinical settings, aircraft, and remote field sites require transcription systems that operate without an internet connection.
Cloud deployment remains the ideal choice for many applications. It offers fast integration, access to maximum model accuracy, and consistent performance across varied end-user hardware.
Local execution involves balancing resource efficiency with model capability. Our on-device models deliver accuracy within 5% relative to our cloud models while running efficiently on edge hardware. For applications where absolute maximum transcription quality is the primary requirement, cloud models provide the top tier of performance.
Evaluating on-device deployment comes down to specific product constraints around data privacy, offline operation, or predictable cost scaling. Where these requirements exist, local transcription delivers substantial value.
The test is whether any of the cases mentioned earlier, the data constraints, lack of network connectivity or the economics of scale applies to you. If there is a clear driver for your business to run the speech-to-text locally then it is worth exploring running on-device.
Selecting an on-device architecture involves balancing accuracy against hardware resource consumption and power efficiency. On-device models are optimized to fit within consumer memory and compute profiles, requiring approximately one CPU core, an optional AI accelerator, and around 800MB of RAM. While ultra-lightweight models exist for simple voice commands, our engine is designed for full-featured transcription, supporting wide accent coverage, speaker diarization, and precise timestamping. You get performance that aligns closely with our cloud model, but that runs locally.
In our benchmarks for Adobe Premiere across 10 million evaluated words, our on-device engine delivered accuracy within 5% relative to our cloud models while outperforming comparable Whisper open-source checkpoints on accuracy by 12% to 16%. The memory consumption for our On-Device is considerably lower - here's how that looks on two laptops, transcribing 20 minutes of clean audio against the best-performing Whisper build in each configuration:
Configuration | Speechmatics on-device | Closest Whisper build |
|---|---|---|
Windows, CPU only | 3.9× real time, 0.94 GB RAM | 1.3× real time, 4.4 GB RAM |
Windows, RTX 4050 GPU | 25.3× real time, 1.7 GB total | 22.1× real time, 3.2 GB total |
Mac M1, CPU only | 4.7× real time, 1.3 GB RAM | 2.8× real time, 3.7 GB RAM |
Mac M1, ANE/GPU | 47.2× real time, 1.1 GB RAM | 11.7× real time, 0.46 GB RAM |
Dell XPS 16 9640 and a 2020 M1 MacBook Pro, transcribing 20 minutes of clean audio. All Whisper builds use Large V3 Turbo - faster-whisper and whisper.cpp on Windows, WhisperKit on Mac. “Total” on the RTX row means RAM plus VRAM, as both engines use the GPU there. These are conservative figures: the Adobe deployment leaves headroom for the rest of the application, so the full optimization set is not enabled.
These are batch results, and batch is the only comparison available since Whisper wasn't designed for streaming. The real-time tools built around it work by chunking audio and stitching the output back together, which costs latency and accuracy at every seam.
Our on-device engine does real-time streaming natively - under 200ms on supported hardware, with the same diarization and timestamping you get in batch. So for live captioning, meeting capture or court reporting, the honest comparison isn't that we're faster than the open-source options. It's that we're doing something they weren't built to do.
Average latency numbers can be deceptive, a low cloud average still leaves you exposed when a user is on unstable hotel Wi-Fi or traveling on a train. Local processing completely removes network round-trip delays and unpredictability, turning latency into a predictable factor determined by local client hardware. On supported hardware, we achieve real-time transcription latency under 200 ms.
Batch processing is equally fast, especially with GPU or AI acceleration. For example, transcribing an hour of audio offline takes under 55 seconds. This transforms video and audio editing workflows, delivering transcripts before you even have time to grab a coffee.
Hardware remains a key factor. While our engine runs reliably on CPUs for both real-time streaming and file batching, utilizing an AI accelerator, such as Apple Silicon or a dedicated Windows GPU, delivers optimal performance. Performance will naturally vary on older or lower-spec machines, which should be accounted for during application design.
Adobe showed us that model optimization is only half the battle. As the first non-linear editor with built-in on-device transcription, they needed reliable execution across an immense variety of end-user configurations ranging in hardware, operating systems, GPU models, and memory limits. Supporting integrations across such hardware diversity is a primary value we bring to partners.
Stenograph presented a very different challenge: court reporting demands low-latency high-accuracy transcription and robust offline operation. Working with a partner whose environment completely rules out cloud connectivity sharpened our focus on building a fully real-time version of our on-device models.
We encourage testing open-source alternatives against real-world audio and real user workflows. What commercial software provides is the gap between a standalone demo and a production-grade product: high-accuracy transcripts, speaker diarization, proper entity formatting, robust handling of heavy accents or background noise, and consistent performance across 55+ languages. You also get a roadmap of future improvements to support your product grow.
You also benefit from dedicated support, ongoing model updates, and clear accountability across releases. In Adobe's evaluations across 10 million words, Speechmatics outperformed comparable Whisper checkpoints by 12% to 16% in accuracy. Whether that difference justifies licensing depends on the cost of errors in your workflow a minor flaw in a voice memo may be acceptable, but not in a legal transcript or clinical record.
Additionally, models like Whisper were not built natively for real-time processing, and running it locally often incurs heavy CPU and memory usage that can degrade other system applications. Speechmatics provides full real-time capabilities with a lightweight resource footprint.
OS-level built-in transcription is another free option, but it is typically platform-bound, and offers limited language support. Ship on both Mac and Windows and you end up maintaining two different speech behaviours and explaining the inconsistency to users. We provide a single, unified library supporting 55+ languages across both macOS and Windows.
Joining early allows engineering teams to gain a market advantage by evaluating local AI capabilities ahead of competitors. Today, our ideal fit is enterprise ISVs and OEMs delivering professional desktop applications for macOS or Windows with dedicated engineering resources capable of integrating a native C/C++ library.
Your team manages audio capture, the application interface, model lifecycle, and update distributions, while we partner with you on core library integration. While current support targets desktop/laptop environments, we are actively exploring expanded device support and proofs-of-concept for broader operating systems.
This architecture is ideal for teams whose products face network reliability constraints, escalating API cost curves at scale, or strict security and compliance requirements.
If you are building a product where local speech-to-text is becoming central to how you sell, join the On-Device waitlist.
We are particularly interested in teams working in legal, media, healthcare, public sector, field services, and high-volume productivity, where local transcription solves a real problem.
And if your situation looks different from anything described here, we would still like to hear about it.
What is on-device speech-to-text?
Speech recognition that runs entirely on the end user's computer or where your application is, rather than on a remote server. The audio and the transcript stay on the machine.
What is the difference between on-device, on-premises, and cloud speech-to-text?
Cloud processes audio on Speechmatics infrastructure. On-prem processes it in containers on the customer's own servers. On-device processes it on the end user's machine, so the audio never leaves the device.
Does on-device speech-to-text reduce transcription costs?
It changes how they scale. Cloud transcription is billed per second, so cost rises with usage by every end user. Once an on-device engine is licensed, the marginal cost of an extra minute is essentially hardware and energy on the end user's machine, and there is no inference infrastructure to run. The saving grows with volume, so it suits high-usage products rather than occasional transcription.
How accurate is on-device speech recognition compared with cloud?
In Adobe's public evaluation, the on-device models delivered accuracy within 5% relative to our cloud models and tested 12 to 16% better than the closest Whisper-powered alternative.
Does it support speaker diarization?
Yes. Speaker diarization runs locally alongside transcription, which is unusual for a model compressed to run on a laptop.
How many languages does it support?
55+ languages at launch, across both batch and real-time, monolingual. If you need multilingual or code-switching output today, that runs in the cloud.
What hardware/OS does it need?
macOS 15 Sequoia or later on Apple M1 or newer, or Windows 11 on Intel, AMD or ARM with a GPU (2GB VRAM minimum). It uses roughly one CPU core, an optional AI accelerator, and around 800MB of system memory. No external GPU or dedicated inference hardware. Android/iOS are coming soon, speak to us if this is something you require.
How do I integrate it, and can I try it today?
You embed a native C/C++ library inside your own application and manage your own audio capture, interface, lifecycle and model updates. It takes more engineering than a cloud API call, and we work alongside your team on it. Access is through the waitlist.

New ways to pay from October 1

End customers will only ever see their own provider's brand, which means the layer underneath has to be good enough to go unnoticed.
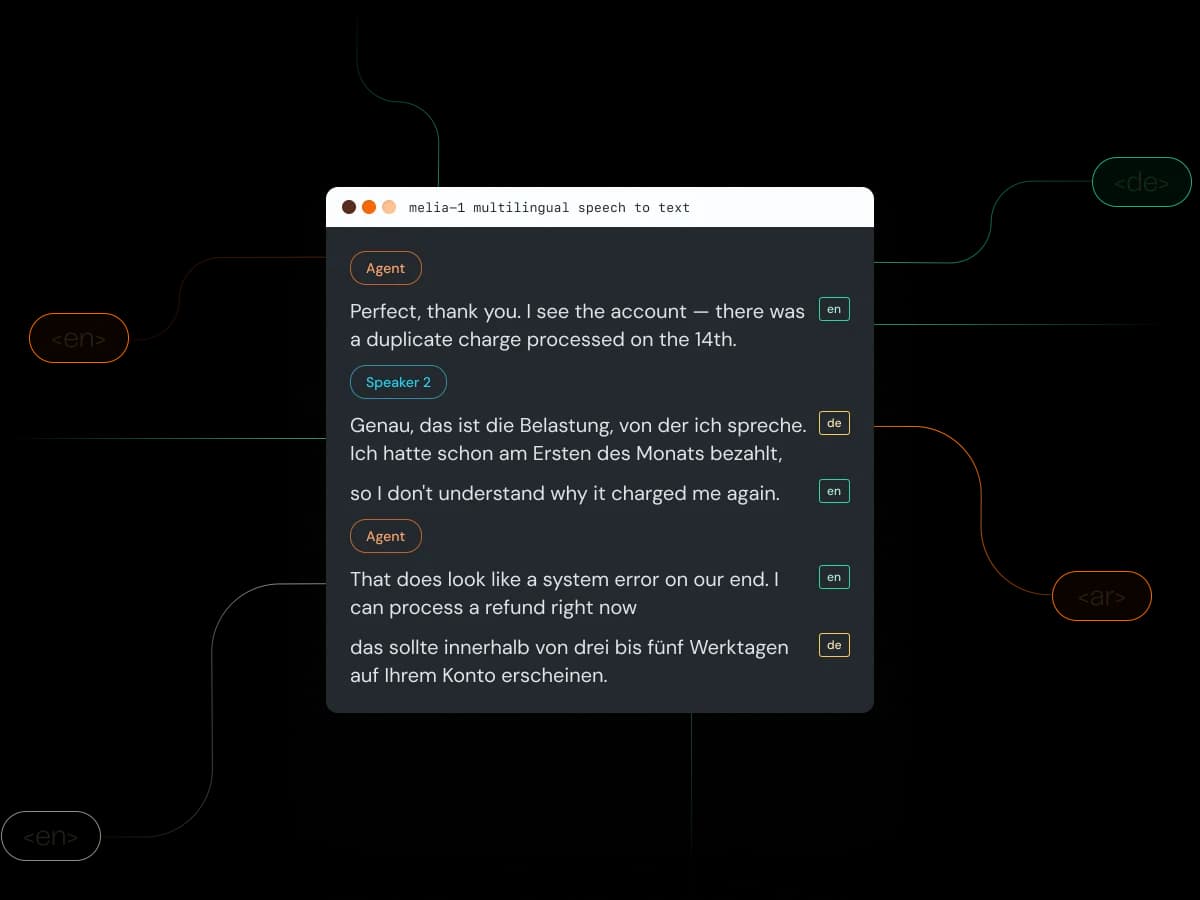
On Arabic and English, Melia 1 runs at less than half the mixed error rate of the next best model. On Mandarin and Tamil it switches more accurately than anything else we tested.

Linden, Speechmatics' new speech-to-text model built for voice agents, is now available through LiveKit Inference, no separate API key, account, or invoice required. Try it out now, click the circle to the bottom right of your screen.

An hour of audio in, a transcript back in under 20 seconds. 30 minutes in under 10 seconds. 10 minutes in under 5 seconds.