SpeechmaticsEditorial Team
In any multi-speaker transcription workflow, one of the biggest challenges is not only turning speech into text. It is working out who said what.
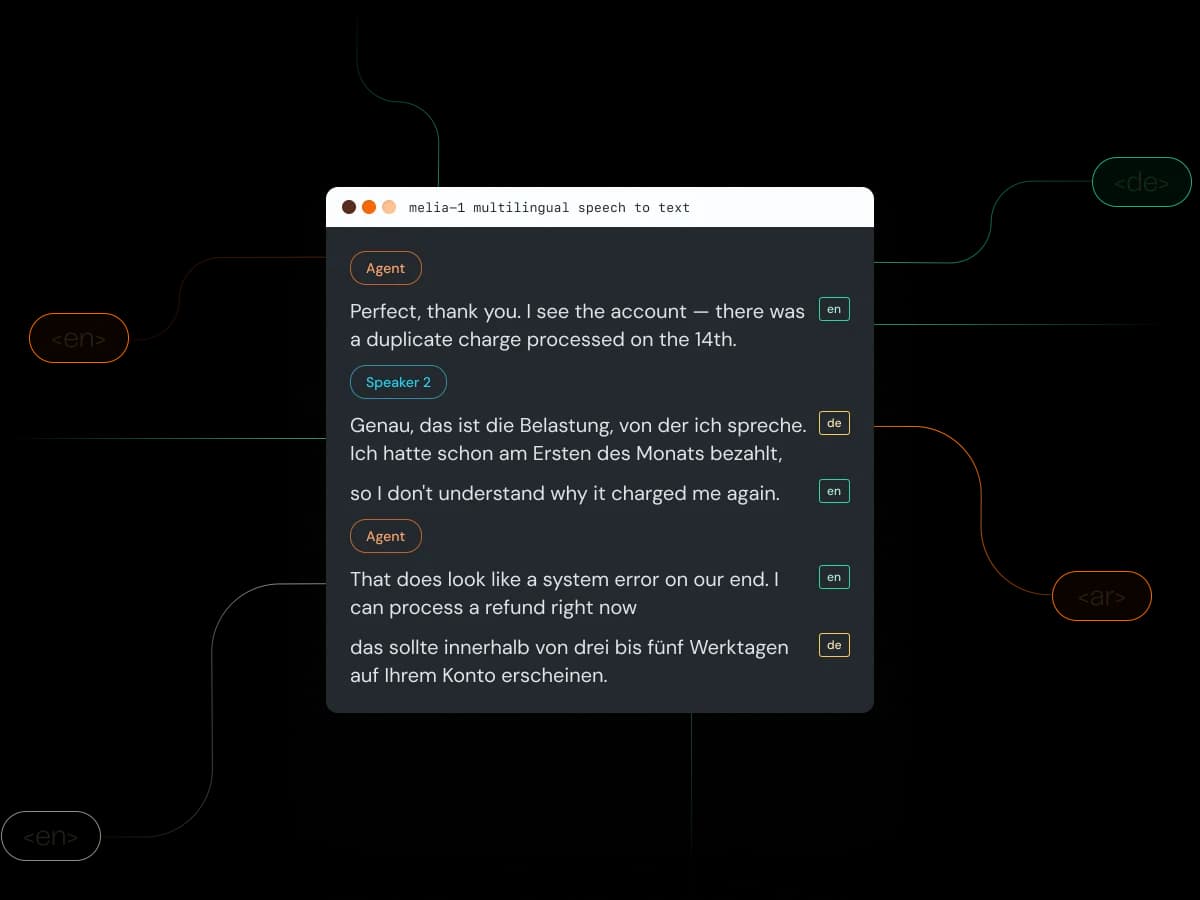
That is where speaker diarisation becomes important. In simple terms, speaker diarisation separates speakers within an audio file or live stream and labels the transcript accordingly. Instead of one block of text from a whole conversation, you get a transcript broken into speaker turns.
For teams working with meetings, interviews, contact centre calls, legal recordings, media content, or research sessions, that changes the value of the transcript completely. Once speaker turns are clear, the transcript becomes much easier to review, search, summarise, and act on.
Speaker diarisation is the process of identifying and separating different speakers in the same audio.
A diarised transcript does not always know the person’s real name automatically. Instead, it may begin by labelling voices as things like:
Speaker 1
Speaker 2
Speaker 3
From there, the transcript can often be reviewed, mapped to real participants, or linked into wider workflow logic.
The key point is that diarisation tells you when the speaker changes. That is what makes it useful in real-world transcription.
Without speaker diarisation, a multi-speaker transcript can quickly become hard to use.
If several people are talking and the output appears as one continuous text stream, teams may struggle to:
Understand the flow of the conversation
Track who asked or answered a question
Review disagreement or escalation points
Pull clear quotes from interviews or meetings
Build accurate summaries or downstream analysis
Diarisation improves structure. It gives the transcript a shape that matches the conversation more closely.
This is especially useful in professional settings where attribution matters as much as the words themselves.
Speaker diarisation is useful anywhere more than one person is speaking and the transcript needs to be reviewed or reused.
Common examples include:
Contact centre calls between agents and customers
Internal team meetings
Board meetings and executive discussions
Broadcast interviews and podcasts
Legal interviews and witness material
Research interviews and focus groups
Medical consultations involving clinicians and patients
In all of these settings, knowing who spoke is a core part of understanding what happened.
Not every transcription use case needs diarisation.
If the audio contains only one speaker, or if the transcript is used only for rough keyword search, diarisation may not add much value. But if attribution, review, summarisation, or analysis matters, it becomes much more important.
A simple way to decide is to ask:
Are there two or more speakers?
Will someone need to understand the conversation structure later?
Does it matter who asked, answered, agreed, or disagreed?
Will the transcript feed QA, compliance, summaries, or analytics?
If the answer is yes, diarisation should usually be part of the workflow from the start.
Like all speech technology, diarisation works best when the input audio is as clear as possible.
That means results are usually stronger when:
Voices are clear and not heavily distorted
Background noise is controlled
Speakers are not all talking over each other constantly
Microphone quality is reasonable
Audio channels are stable and not cutting in and out
Diarisation can still work in difficult conditions, but cleaner audio makes speaker changes easier to detect and improves the overall transcript quality too.
This is especially important in live enterprise settings where low latency and consistent recognition quality matter. Providers such as Speechmatics are often used in these workflows because they combine low-latency multilingual speech-to-text with diarisation support across a wide range of real-world use cases.
A key workflow decision is whether diarisation needs to happen live or after the event.
Real-time diarisation is useful when you need speaker-labelled text during the conversation itself.
This can support:
Live meeting captions
Contact centre support tools
Live compliance monitoring
Real-time note generation
Agent assist or meeting assist workflows
Real-time use requires stronger performance around latency and speaker switching.
Batch diarisation happens after the audio is complete.
This is often used for:
Meeting records
Interview transcription
Media archive processing
Legal and research review
Post-call analytics
Batch workflows can often use more complete context from the full recording, which may improve the final structure of speaker turns.
One of the biggest mistakes teams make is treating speaker diarisation as an optional extra after transcription has already been designed.
It works better when it is part of the workflow from the start.
That means deciding early:
Where the transcript will be used
Whether speaker labels need to be visible to end users
Whether speaker turns feed summaries or analytics
Whether users need to rename speakers later
Whether the transcript needs exporting into another system
If diarisation is treated as a core input, downstream tools can be designed to make much better use of it.
In many workflows, diarisation begins with anonymous speaker labels rather than personal names.
That raises a practical question: what should happen next?
Common approaches include:
Leaving generic labels in place where only speaker separation matters
Renaming speakers manually in a review interface
Matching speakers to metadata from the meeting or call system
Mapping speaker roles such as Agent and Customer in contact centre use
The right approach depends on the use case. In a podcast edit, real names may matter. In QA review, Agent and Customer may be enough. In a legal transcript, a verified identity link may be critical.
One of the strongest uses of speaker diarisation is in transcript summarisation.
When the system or reviewer can see who said what, summaries become easier to structure around:
Questions and answers
Actions and owners
Agreements and decisions
Concerns raised by specific people
Customer requests and agent responses
Without speaker separation, many summaries become flatter and less useful because the transcript has lost the shape of the interaction.
This is one reason diarisation matters so much in enterprise voice AI. It helps convert raw conversation into more meaningful downstream output.
Diarisation is valuable, but it is not magic.
One of the hardest cases is overlapping speech, where two or more people talk at once. In these moments, attribution can become more difficult, especially in noisy or fast-moving recordings.
That does not mean diarisation stops being useful. It means teams should understand where errors are most likely and build review processes around the parts of the workflow that matter most.
For example, a contact centre QA team may accept occasional overlap issues in exchange for wide transcript coverage. A legal workflow may require much tighter human review around disputed passages.
In regulated sectors, speaker separation can be especially valuable because it helps teams distinguish who made which statement.
For example, diarisation can support:
Customer vs agent statement tracking
Required script monitoring
Dispute review
Call scoring
Complaint handling
Vulnerability detection
This is where secure enterprise deployment matters. In sensitive settings, the value of diarisation depends not only on transcription accuracy but also on how audio and transcripts are handled overall. Speechmatics places strong emphasis on enterprise deployment flexibility, including cloud, on-prem, and on-device options, alongside privacy-focused principles such as no data logging by default.
Before rolling out speaker diarisation widely, test it on the kinds of conversations your business actually handles.
Useful test cases might include:
Calm, structured meetings
Fast-paced support calls
Interviews with interruptions
Group discussions with several speakers
Noisy or lower-quality recordings
This helps you understand:
How reliably speaker turns are identified
What happens in overlap-heavy audio
Whether the output is usable for your downstream tasks
How much human review is still needed
A good pilot is usually more valuable than a long feature list.
Even strong diarisation benefits from occasional review.
That is why teams should think about the reviewer experience as well as the model output. Useful review workflows often include:
Easy speaker relabelling
Quick correction of speaker-change points
Searchable transcript structure
Export options for edited transcripts
Integration into QA or documentation tools
If the review layer is clumsy, users may stop trusting the transcript even when the diarisation is mostly correct.
If your organisation handles conversations in multiple languages, diarisation should be considered alongside multilingual transcription, not separately.
This matters because global enterprises often want one platform that can support several languages without splitting workflows across different tools. Speechmatics supports 56+ languages, which makes it easier for multilingual teams to apply the same speaker-aware transcription model across different markets and departments.
Speaker diarisation is one of the most useful ways to improve multi-speaker transcription workflows because it turns raw conversation into structured, attributable text.
That structure makes transcripts easier to review, summarise, analyse, and trust. It matters in meetings, contact centres, media, legal work, research, and any enterprise workflow where more than one person is speaking and attribution changes the meaning.
The best results usually come when diarisation is designed into the workflow from the beginning. When teams think carefully about audio quality, review needs, deployment model, and downstream use, speaker diarisation becomes much more than a feature. It becomes a practical way to make multi-speaker transcription genuinely usable at scale.