SpeechmaticsEditorial Team
Real-time transcription looks simple from the outside. Audio goes in, text comes out. In practice, the hard part is not getting a transcript at all. It is getting one fast enough, accurate enough, and scalable enough for a real product.
That is why developers evaluating speech-to-text APIs need to look beyond a basic demo. A model that performs well in a quiet test clip may struggle in a live meeting, a contact centre workflow, or a multilingual media stream. Latency, accuracy, and scaling are not separate concerns either. They shape each other.
This guide explains what developers should pay attention to when building with real-time transcription APIs and how to think about trade-offs before going to production.
In development terms, real-time transcription means speech is processed quickly enough for the text output to be useful while the speaker is still talking, or very shortly after.
That matters for use cases such as:
Live captions
Meeting assistants
Contact centre agent support
Broadcast subtitling
Voice interfaces
Live compliance monitoring
In all of these cases, speed is part of the product. If the transcript appears too late, it may still be technically correct, but it is no longer doing the job users need.
Latency is usually the first thing developers notice because it affects user experience immediately.
If text appears almost as soon as someone speaks, the system feels responsive. If the output lags too far behind, the experience starts to break down.
There are a few different ways to think about latency.
This is the delay between speech being captured and reaching the transcription system.
This is how long the model takes to turn incoming audio into text.
This is how long it takes for the user or downstream system to receive the transcript.
A real-time API may look fast in marketing, but developers should still ask where the delay sits. In many live applications, even a modest extra delay can make a visible difference.
Latency usually comes from a mix of issues rather than one single bottleneck.
Common causes include:
Slow audio chunking or buffering
Poor network conditions
Heavy model processing time
Inefficient streaming implementation
Long post-processing stages
Delays in delivering partial or final results
This is why testing with realistic conditions matters. A low-latency API should not only perform well in perfect lab conditions. It should stay usable under actual traffic, mixed audio quality, and production network behaviour.
Accuracy matters, but developers need to think carefully about what kind of accuracy their product actually needs.
For some applications, basic word recognition may be enough. For others, the system needs to handle:
Domain-specific vocabulary
Brand names
Numbers and amounts
Speaker overlap
Punctuation
Multilingual switching
Strong accents or fast speech
That is why raw accuracy scores alone do not tell the full story. A model may perform well on generic benchmarks and still struggle with your actual user environment.
A few factors usually have the biggest impact.
Bad microphones, compression, background noise, and dropped packets all reduce accuracy.
People interrupt each other, trail off, restart sentences, and speak unclearly. Real-time systems need to handle this better than simple dictation tools.
Technical, medical, legal, or industry-specific language often needs stronger vocabulary handling than general-purpose speech models.
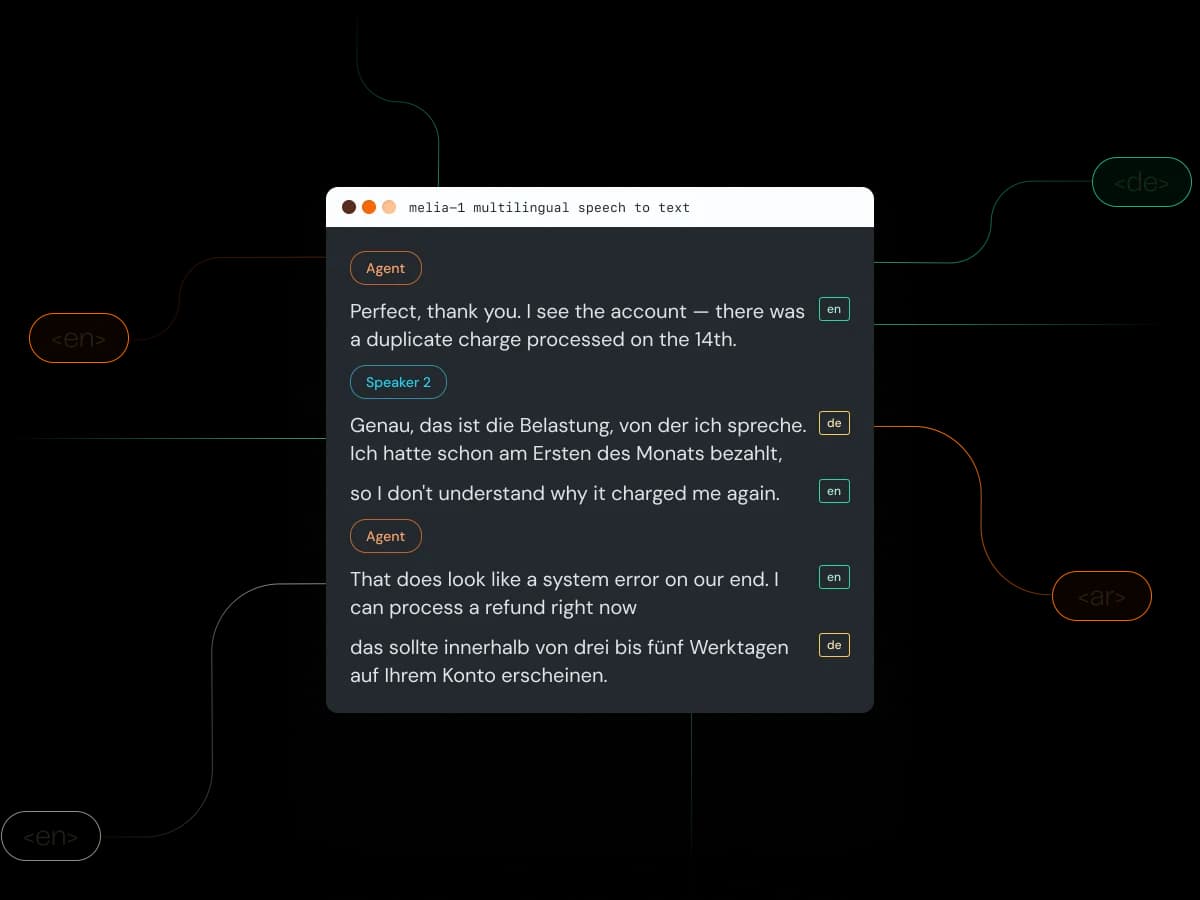
If your users operate across multiple countries, multilingual support becomes a real product requirement rather than a nice extra.
This is one reason developers often look closely at providers with broad enterprise coverage. Speechmatics, for example, supports low-latency transcription across 56+ languages and positions its platform around flexible deployment for global voice workflows.
One of the most important design choices in a real-time transcription API is how it handles partial output.
Most real-time systems do not wait until the speaker finishes completely before returning text. They send partial hypotheses as the sentence develops, then refine them.
This creates a trade-off:
Faster partial results improve responsiveness
Later final results may improve accuracy and punctuation
Developers need to decide what their application should show, store, or act on.
For example:
Live captions may show partial text quickly and refine it in place
Compliance systems may rely more heavily on finalised output
Agent-assist tools may use partial text for speed, then log final text later
The right balance depends on the workflow.
A transcription demo usually handles one stream well. Production systems rarely stop there.
At scale, developers need to think about:
Number of concurrent streams
Burst traffic
Global traffic patterns
Failover and resilience
Throughput for mixed workloads
Cost control per usage level
This is where a strong API architecture matters. A platform that feels quick in a low-volume test may behave very differently once hundreds or thousands of live sessions run at once.
Before building too far, developers should ask:
How many simultaneous sessions do we need to support?
Are these short bursts or long-running streams?
Do we need global routing?
What happens under failover?
How do we monitor stream health and response time?
Can the system support both live and batch workflows if needed?
These questions are often more important than feature lists, because scaling problems usually appear after the product is already in front of users.
The API is only one part of the experience. Your application architecture also affects performance.
Design decisions around:
WebSocket or streaming protocol choice
Chunk size
Retry logic
Session lifecycle handling
Client buffering
Backpressure handling
can all influence how well the transcription performs.
A high-quality speech engine can still feel slow if the application sends audio inefficiently or handles reconnection badly.
Developers also need to think about deployment fit.
Different projects may need different approaches:
Cloud for fast implementation and elastic scale
On-prem for tighter security and enterprise control
On-device for edge use cases or reduced dependency on connectivity
In enterprise environments, this becomes especially important where security, compliance, and data-handling rules shape architecture decisions. Speechmatics supports cloud, on-prem, and on-device deployment options, which is useful for teams building products across different risk and infrastructure models.
For enterprise use cases, security should never be left until late in the build.
Real-time transcription may involve:
Customer calls
Internal meetings
Legal recordings
Medical discussions
Sensitive financial information
That means developers need to understand:
Where audio is processed
Whether data is logged or retained
How access is controlled
What compliance standards apply
Whether the deployment model fits the organisation’s policies
This is often where vendor choice becomes much more serious than simply choosing the cheapest or fastest-looking API.
A good evaluation should go beyond a clean sample clip.
Test with:
Real microphones
Real background noise
Real user accents
Real domain vocabulary
Real concurrency patterns
Real network conditions
Look at:
Time to first transcript
Stability of partial results
Final result quality
Behaviour under load
Error handling and session recovery
Language support where relevant
The goal is not only to ask whether the API works. It is to ask whether it works in your product, at your expected scale, with your users.
A few problems come up again and again.
Headline accuracy scores are useful, but they are not the same as production fit.
Users often judge the system by what appears first, not only by the final transcript.
Real-world audio is usually much messier than demo clips.
Low-latency streaming at scale needs careful operational planning, not just an API key.
Enterprise teams often hit delays when data handling and deployment questions are addressed only after the prototype is already built.
A real-time transcription API should be judged on more than whether it can turn speech into text. Developers need to look closely at latency, accuracy, and scaling together, because a strong production system depends on all three.
Fast transcripts that are unusable are not enough. Accurate transcripts that arrive too late are not enough either. And neither matters much if the system cannot scale under real demand.
The best approach is to test with realistic audio, define the product need clearly, and evaluate the API in the same conditions your users will face. When you do that, it becomes much easier to choose a transcription platform that supports not only a proof of concept, but a real product.